facebook-pages-scraper


Facebook Pages Scraper
Facebook Pages Scraper reads public Facebook page info and the latest post without a browser or an API key. If you find it useful, please support the package by hitting the star on GitHub. Your support helps keep the project going.
Use facebook-pages-scraper for a page name, intro, about text, contact fields, and the latest post. A string returns one result. A list returns one result per page. Works with pip install facebook-pages-scraper or uv add facebook-pages-scraper on Python 3.11+.
Looking for a sponsor
ssujitxx@gmail.comDemo
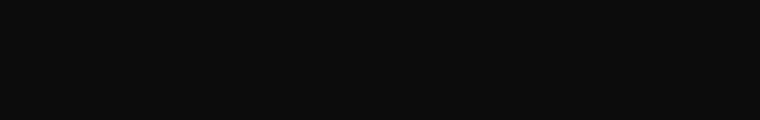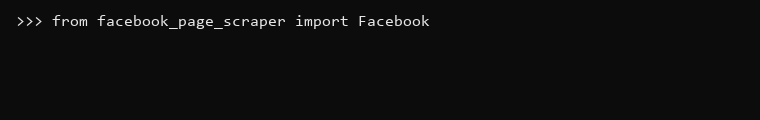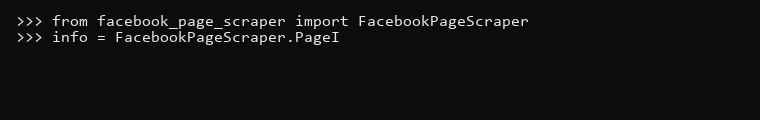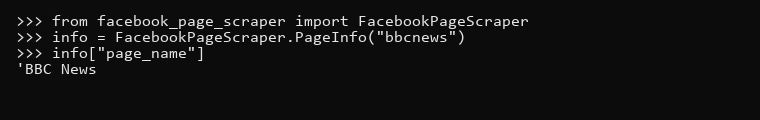
How it works
The package fetches the public page HTML with a Chrome-like client, then reads the JSON Facebook embeds in that document.
Page info comes from the profile header and intro cards. Address, the About paragraph, page id, and creation date come from the About tab. The first HTML document includes only the latest post.
Accepted input:
bbcnewshttps://www.facebook.com/bbcnewshttps://web.facebook.com/bbcnewshttps://m.facebook.com/bbcnews
pizzaburgbd is a public page that fills the About fields: intro, about text, address, phone, email, website, hours, services, Instagram, owner, page id, and creation date. Use it when you want a test run to show a full result. Page likes and the Monday–Sunday hours grid are still absent, because Facebook does not put them in this HTML.
A string returns one dict (or one list of posts). A list returns one result per page, in order. A failed page is None.
page_social_accounts is a map of network to link, for example {"Instagram": "https://www.instagram.com/meta"}. Page likes are often missing from the public HTML. page_business_hours is the open/closed line Facebook sends with the page, not the Monday–Sunday grid.
Installation
uv add facebook-pages-scraper
pip install facebook-pages-scraper
pip install facebook-pages-scraper --upgrade
This repo uses uv:
uv sync --group dev
Parameters
| Parameter | Default | What it is |
|---|---|---|
url |
required | One page URL or username, or a list of them. |
proxy |
None |
Optional HTTP/HTTPS/SOCKS5 proxy if this IP is rate-limited. |
concurrency |
4 |
Async list only. Max pages fetched at once. |
proxy stays None unless you need one. Examples:
http://user:pass@host:port
https://host:port
socks5://user:pass@host:port
Usage
Sync — PageInfo
from facebook_page_scraper import FacebookPageScraper


def main():
    # Optional. Examples:
    #   proxy = "http://user:pass@host:port"
    #   proxy = "https://host:port"
    #   proxy = "socks5://user:pass@host:port"
    proxy = None

    url = "https://web.facebook.com/pizzaburgbd"

    try:
        page = FacebookPageScraper.PageInfo(url, proxy=proxy)
        if page:
            print(page)
        else:
            print("Error: no page data")
    except Exception as e:
        print(f"Error occurred: {e}")


if __name__ == "__main__":
    main()
Async — PageInfoAsync
import asyncio

from facebook_page_scraper import FacebookPageScraper


def main():
    # Optional. Examples:
    #   proxy = "http://user:pass@host:port"
    #   proxy = "https://host:port"
    #   proxy = "socks5://user:pass@host:port"
    proxy = None

    url = "https://web.facebook.com/pizzaburgbd"

    try:
        page = asyncio.run(FacebookPageScraper.PageInfoAsync(url, proxy=proxy))
        if page:
            print(page)
        else:
            print("Error: no page data")
    except Exception as e:
        print(f"Error occurred: {e}")


if __name__ == "__main__":
    main()
Async batch
Pass a list. Up to concurrency pages run at once.
import asyncio

from facebook_page_scraper import FacebookPageScraper


def main():
    # Optional. Examples:
    #   proxy = "http://user:pass@host:port"
    #   proxy = "https://host:port"
    #   proxy = "socks5://user:pass@host:port"
    proxy = None

    urls = [
        "https://web.facebook.com/pizzaburgbd",
        "https://web.facebook.com/NASA",
        "https://web.facebook.com/Meta",
    ]

    try:
        pages = asyncio.run(
            FacebookPageScraper.PageInfoAsync(urls, concurrency=4, proxy=proxy)
        )
        for page in pages:
            if page:
                print("Page:", page["page_name"])
            else:
                print("Error: no page data")
    except Exception as e:
        print(f"Error occurred: {e}")


if __name__ == "__main__":
    main()
FacebookPageScraper.PageInfo(urls) also accepts a list (sync, one page after another). For many pages, async batch is the better call.
PagePostInfo and PagePostInfoAsync take the same url, proxy, and concurrency arguments. A string returns the latest post as a one-item list. A list of pages returns a list of those lists.
Disclaimer
Facebook’s Terms of Service and Community Standards prohibit unauthorized scraping of their platform. This package is intended for educational purposes, and you should use it in compliance with Facebook’s policies. Unauthorized scraping or accessing Facebook data without permission can result in legal consequences or a permanent ban from the platform.
By using Facebook Pages Scraper, you acknowledge that you have the right to access the data you are scraping, and that you are solely responsible for how you use this package. The developers of this tool are not liable for any misuse.